Fast, efficient, state-of-the-art document understanding in a single model

LightOnOCR-3 is our new family of end-to-end OCR models, built to deliver leading performance with speed and efficiency. It goes beyond text transcription to recover document structure, locate content on the page, describe images and turn charts into usable data, all through a single model call.

LightOnOCR-3 turns complex documents into structured content that applications can use directly.
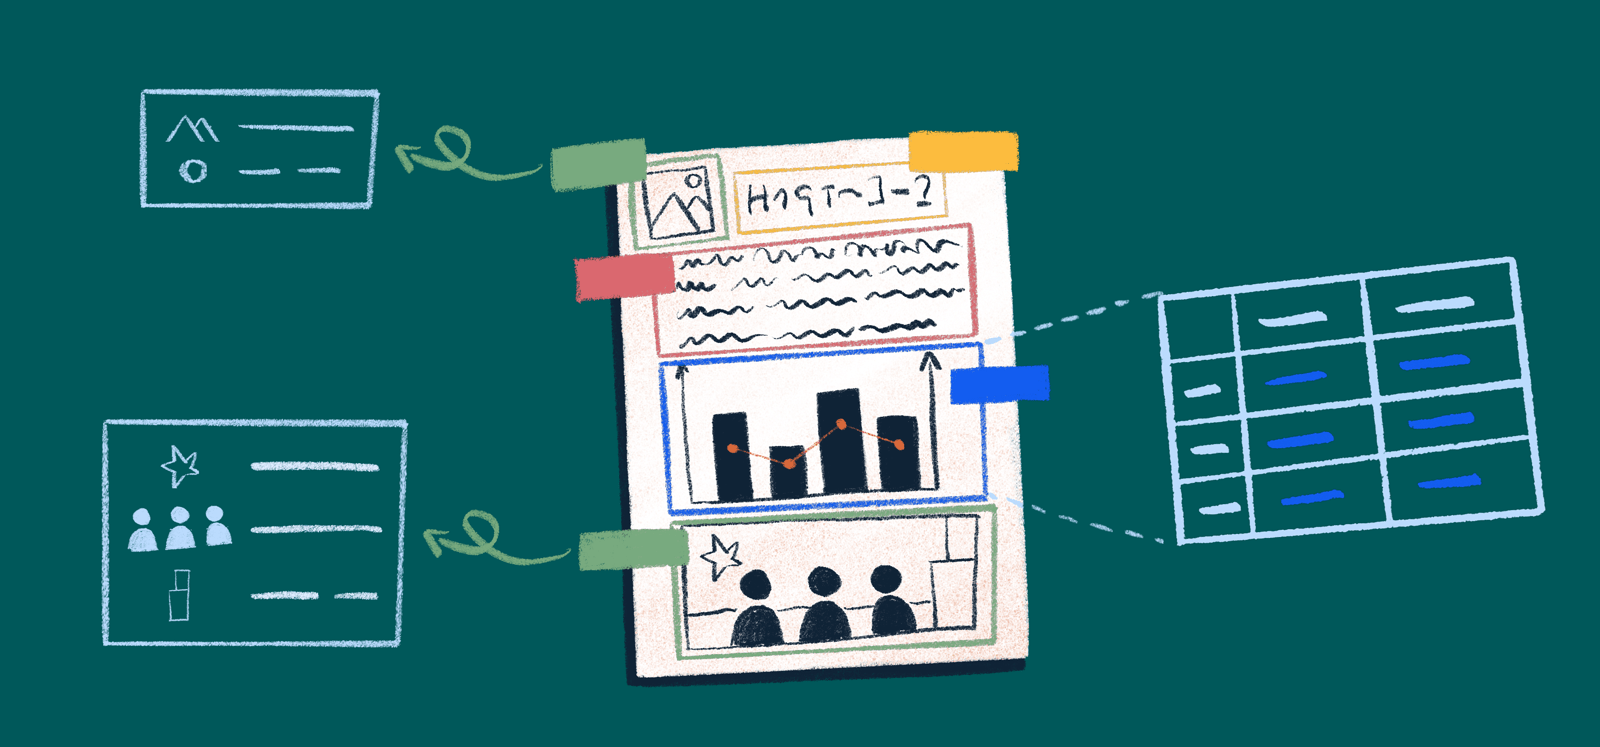
A document page whose image, text, chart and photo blocks are each labelled and extracted: images to descriptions, the chart to a data table.

Building on the success of LightOnOCR, with more than 4.5 million downloads on Hugging Face, this new family of end-to-end OCR models goes beyond accurate text transcription: it identifies and locates layout elements, describes images, and extracts data from charts and scientific figures.
  • Leading transcription accuracy in compact models: Our models have leading results across three open benchmarks: first on FRBench-pdf2md, with particular strengths in handwriting, second on OlmOCR-Bench, and first among open-weight models on ParseBench.
  • Document structure and content-aware chunking: The model groups content into logical paragraphs, headings, tables and other document elements, each with a label and bounding box. These spatially grounded blocks support downstream chunking, retrieval and links back to the original page.
  • Image descriptions and structured chart data: LightOnOCR-3 models describe images and extract data from charts, plots and scientific figures, making visual information accessible to search and analysis alongside the document’s text.
  • Single models that can be prompted in two modes: A simple prompt change switches between plain transcription, matching LightOnOCR-2 output, and richer grounded output.
From OCR to document understanding

Traditional OCR pipelines combine several specialized components, combining models used for layout detection, transcription, additional logic for tables and charts, and custom processing to reconnect every extracted element to its position on the page… The systems can perform well, however they are difficult to build, maintain and scale.

LightOnOCR-3 brings us closer to our long standing goal of having a single model as a replacement for complete OCR pipelines. Additionally to improved transcription quality, it is trained to return a grounded representation of the page that provides layout structure, image descriptions as well as chart data extraction.

No more pipelines, a single model is all you need to build highly performant workflows for search, extraction or RAG applications.

The model is designed for developers and engineering teams building applications on top of complex business, technical and scientific documents.

Strong performance in a compact model

LightOnOCR-3 delivers leading results across aggregated benchmarks for text recognition and the interpretation of visual information, they are additionally among the fastest on the market, processing documents twice as fast as LightOnOCR-2. They are also the cheapest among leading OCR models. When run on an organization’s own infrastructure, processing costs can fall below one cent per thousand pages, depending on hardware, usage levels and workload.

In self-hosted deployments, processing costs can fall below one cent per thousand pages, depending on hardware, utilization and workload, offering a low-cost high performance alternative to commercial OCR services such as Mistral OCR.

Structure, not just transcription

The models can be used as before in a transcription-only mode, where all textual elements of the page are outputted, if you’re currently using our previous models switching to v3 requires no change as it’s the default behavior when calling it with an empty prompt.

The new usage mode is to call the models with the grounding prompt. It will then output all the new vision features alongside transcribed text.

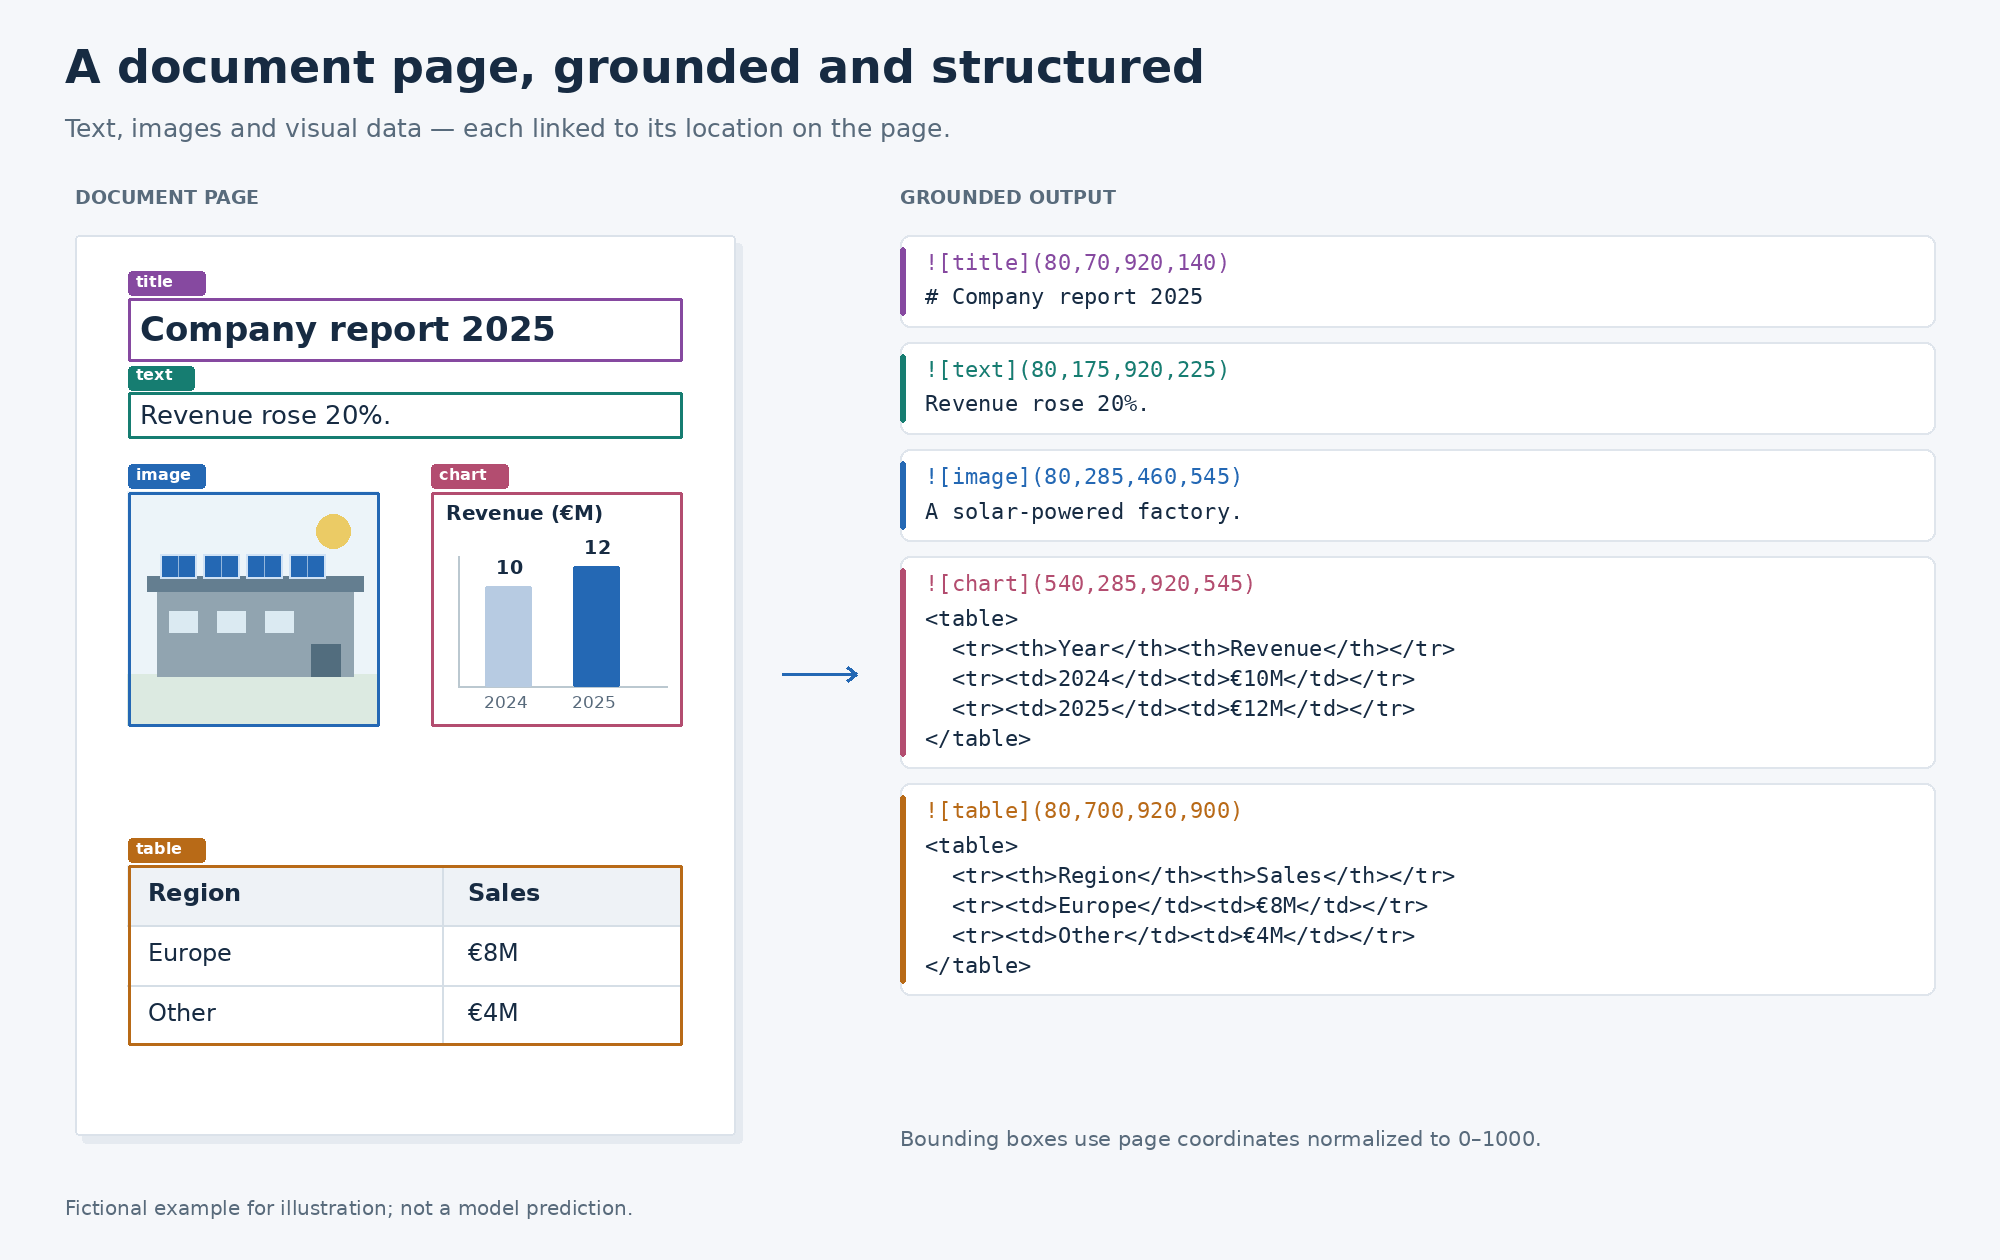
A document page with its title, text, image, chart and table outlined, beside the grounded output: each block's label and bounding box, then its text, image description or HTML table.

LightOnOCR 3 can identify document elements and return their bounding-box coordinates, preserving where paragraphs, tables, images and other blocks appear on the original page. Each block of content is now enriched depending on the nature of the block:

  • Textual content blocks contain the transcribed content of paragraphs, titles and other text elements.
  • Image blocks pair a bounding box with a short description, making visual content accessible to retrieval and question-answering pipelines.
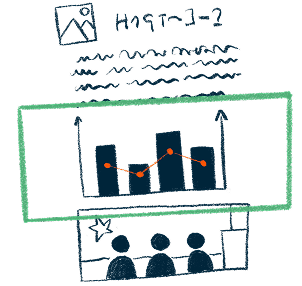
  • Chart blocks contain an HTML table of data points extracted from the figure, transforming visual information into structured data for reporting, analysis and retrieval.

Built for downstream document workflows

The structured output unlocks several common workloads:

  • RAG and enterprise search: Create cleaner, layout-aware chunks and retain the location of supporting content for grounded answers and citations.
  • Document extraction: Recover text, tables, charts and other elements from complex business documents without maintaining separate parsers for each content type.
  • Knowledge-base ingestion: Convert heterogeneous documents into consistent, typed content before indexing.
  • Document agents: Give agents both the content of a document and the structural context needed to act on forms, reports and records.
  • Scientific and technical document processing: Preserve equations, tables, figures and chart data that basic OCR pipelines often flatten or lose.

Benchmark performance

  1. 01LightOnOCR-3 4B78.5
  2. 02LightOnOCR-3 0.8B76.9
  3. 03Infinity-Parser2-Pro75.0
  4. 04chandra-ocr-275.0
  5. 05Mistral OCR 469.2
  6. 06surya-ocr-267.4
  7. 07dots.mocr66.3
  8. 08jina-ocr-v160.9
  9. 09LightOnOCR-2 1B---
Overall score
Show data
Average and benchmark scores per model
ModelAverageolmOCRParseBenchfr-bench-pdf2md
LightOnOCR-3 4B78.586.375.174.1
LightOnOCR-3 0.8B76.985.574.670.5
Infinity-Parser2-Pro75.087.674.363.2
chandra-ocr-275.085.870.169.0
Mistral OCR 469.285.268.254.1
surya-ocr-267.483.364.854.1
dots.mocr66.383.955.859.3
jina-ocr-v160.983.445.953.2
LightOnOCR-2 1BNot available83.248.0Not available

Model size & performance

75808590950.712481632Model parameters (B, log scale) • Smaller is betterOverall score • Higher is betterMistral OCR 4: 85.2 points, size undisclosed · Reported results · reference only, excluded from the size Pareto frontierMistral OCR 4† · 85.2Infinity-Parser2-Pro: 87.6 points, 35.1B parameters · Reported results · Pareto frontierInfinity-Parser2-Pro†chandra-ocr-2: 85.8 points, 4.0B parameters · Output with post-processingchandra-ocr-2†dots.mocr: 83.9 points, 3.0B parameters · Reported resultsdots.mocrjina-ocr-v1: 83.4 points, 3.4B parameters · Reported resultsjina-ocr-v1surya-ocr-2: 83.3 points, 0.7B parameters · Output with post-processing · Pareto frontiersurya-ocr-2†LightOnOCR-2-1B: 83.2 points, 1.0B parameters · Reported results · different overall definition, excluded from frontierLightOnOCR-2LightOnOCR-3-4B: 86.3 points, 4.0B parameters · Output with post-processing · Pareto frontierLightOnOCR-3 4B†LightOnOCR-3-0.8B: 85.5 points, 0.8B parameters · Output with post-processing · Pareto frontierLightOnOCR-3 0.8B†
  • External models
  • LightOnOCR-2
  • LightOnOCR-3
  • Pareto frontier

Hover or focus a point for its exact checkpoint and scores.

Show data
olmOCR-Bench: plotted scores
ModelSize (B)OverallOutput / inputsFrontier
Infinity-Parser2-Pro35.187.6Reported resultsYes
LightOnOCR-3-4B4.086.3Output with post-processingYes
chandra-ocr-24.085.8Output with post-processingNo
LightOnOCR-3-0.8B0.885.5Output with post-processingYes
Mistral OCR 4Undisclosed85.2Reported resultsSize undisclosed
dots.mocr3.083.9Reported resultsNo
jina-ocr-v13.483.4Reported resultsNo
surya-ocr-20.783.3Output with post-processingYes
LightOnOCR-2-1B1.083.2 *Reported resultsExcluded *

Try it now

Build faster document pipelines with text, layout and visual understanding from a single compact model.

The LightOnOCR-3 4B model card on Hugging Face.